
In modern sports analytics architecture, live cricket represents one of the most computationally complex disciplines to model and price dynamically. Unlike fixed-time field sports with contiguous gameplay, cricket consists of discrete, highly structured events—deliveries, overs, wickets, extras, and tactical powerplays—interspersed with physical and environmental variables such as pitch degradation, atmospheric humidity, and ball wear. The acceleration of high-frequency formats like Twenty20 (T20) and T10 has pushed data processing requirements toward low-latency automated systems capable of ingesting stadium telemetry and outputting updated probabilities within milliseconds.
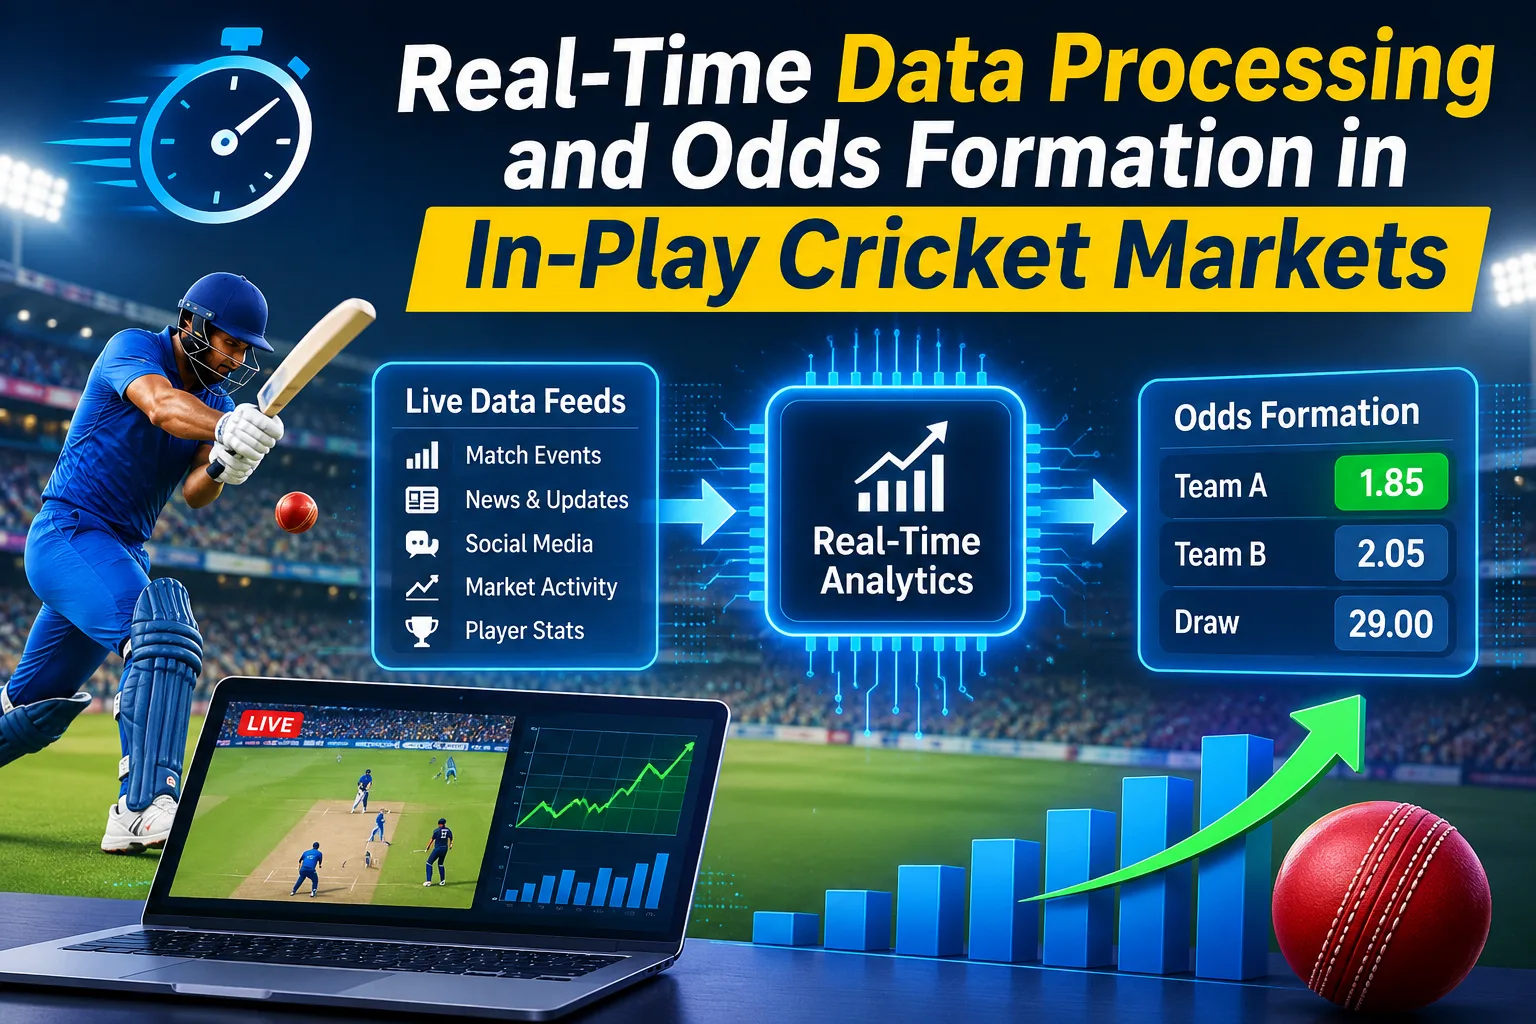
To maintain market stability and balance risk across concurrent micro-markets, platforms rely on real-time data ingestion pipelines that convert physical delivery variables into calibrated probability distributions. When raw event telemetry flows from pitch-side data operators or optical tracking arrays into pricing engines, risk management algorithms must instantaneously recalculate main match winner outcomes, individual over totals, and player prop lines before the bowler initiates the subsequent run-up.
How Real-Time Data Feeds Drive In-Play Cricket Odds
The primary layer of live cricket infrastructure rests on multi-source data ingestion. Primary data providers position dedicated scouts in stadium media boxes equipped with specialized handheld terminals to log event codes directly over encrypted low-latency sockets. Supplemental feeds from optical camera setups, including Hawk-Eye and PitchVision systems, capture spatial coordinates such as release velocity, pitch point, seam angle, and deviation off the surface. Combining these data streams enables automated engines to re-evaluate match state vectors after every ball rather than relying on delayed post-over summary data.
Modern sports technology architectures rely on continuous data ingestion from official scouting feeds and stadium telemetry to calculate real-time win factors. When evaluating how digital interfaces render these rapidly shifting probabilities during high-tempo T20 or international matches, platforms facilitating desi cricket live betting online demonstrate how real-time WebSocket connections deliver sub-second updates for dynamic markets such as next-ball outcomes, over total runs, and method of dismissal. This continuous flow of structured data ensures that odds reflect precise pitch-side developments, reducing price slippage and minimizing latency arbitrage for active participants.
Market integrity in high-frequency sporting environments depends heavily on automated suspension protocols. Whenever a high-leverage event occurs—such as a boundary strike, a wicket appeal, or a Decision Review System (DRS) referral—the trading engine temporarily halts order matching on affected micro-markets. This controlled suspension window mitigates the risk of stadium-based latency advantages, commonly known as court-siding. Once the official third-umpire ruling or ball confirmation is broadcast over the primary feed, the pricing engine recalculates the state matrix and automatically reopens order queues with refreshed implied probability curves.
Mathematical Modeling and In-Play Recalibration Engines
Algorithmic models for live cricket pricing must account for non-linear probability changes driven by dynamic required run rates, remaining wickets, and pitch condition decay. Static pre-match models that rely exclusively on historical team averages fail during live match scenarios where tactical context heavily dictates expected value. For instance, requiring 42 runs off 24 deliveries presents vastly different mathematical expectations depending on whether the batting side retains eight wickets or two, or whether the current surface exhibits pronounced turn for spin bowling.
To calculate accurate market lines under shifting conditions, quantitative engines combine stochastic simulation models with Duckworth-Lewis-Stern (DLS) mathematical principles. Monte Carlo engines execute thousands of simulated match completions in the fractional second following each ball outcome, factoring in historical batter performance against specific bowling types, stadium boundary dimensions, and active field restrictions.
| Feed Category | Primary Data Source | Typical Latency Range | Primary Technical Function |
|---|---|---|---|
| Official Scout Telemetry | In-stadium manual input consoles | 200ms – 500ms | Immediate state updates (runs, wickets, extras) |
| Optical Ball Tracking | Multi-camera Hawk-Eye radar arrays | 800ms – 1.5s | Detailed spatial trajectory and pitch point data |
| Broadcast Satellite Feed | Over-the-Top / Television broadcast | 3.0s – 12.0s | Visual confirmation and video playback |
| Automated Pricing Engine | Algorithmic risk management models | 50ms – 150ms | Dynamic line calculation and distribution |
Machine learning models trained on historical T20 datasets continuously refine pitch factor metrics during play. In evening fixtures, for example, the accumulation of dew on the outfield reduces ball friction, making spin bowling less effective while allowing the ball to skid on predictably for batters. Quantitative engines integrate atmospheric sensor data and relative humidity readings to automatically decay the defensive rating of spin overs during second-innings run chases.
System Resilience and High-Concurrency Management During Peak Events
Major international tournaments and high-profile domestic leagues generate severe traffic surges on real-time data distribution layers. During the closing overs of a tight chase, concurrent socket connections scale dramatically as client devices request continuous market updates. System architects preserve operational uptime by decoupling core pricing calculation clusters from client-facing delivery networks through distributed caching patterns.
In a resilient high-concurrency setup, pricing engine instances broadcast updated odds directly into an in-memory data store like Redis or an Apache Kafka message stream. Edge servers distributed across global Content Delivery Networks (CDNs) read from these event streams and fan out stateless WebSocket or Server-Sent Events (SSE) connections to end users. This publisher-subscriber separation insulates primary quantitative calculation nodes from direct incoming client traffic, preventing API rate-limiting degradation during match-winning moments.
To further guarantee service availability against network partitioning or hardware node failures, platform engineers implement microservice redundancy and distributed consensus protocols. If a primary pricing worker fails, a redundant secondary instance assumes the state calculation pipeline from the shared event broker within milliseconds, ensuring zero transactional loss or service interruption.
Key Architectural Requirements for Live Sports Analytics
Constructing a reliable processing pipeline for high-frequency sports data demands strict engineering discipline across network and data storage tiers. Technical teams evaluate platform health through four primary architectural benchmarks:
- Data Serialization Efficiency: Employing compact binary transport formats like Protocol Buffers (protobuf) or FlatBuffers rather than verbose JSON payloads to minimize bandwidth overhead on mobile networks.
- State Storage Isolation: Keeping real-time match state matrices isolated from primary relational databases to ensure read and write operations never block main pricing execution threads.
- Automated Data Anomaly Detection: Deploying algorithmic validation checks that flag conflicting telemetry inputs between independent data vendors, preventing mispriced lines caused by human logging errors.
- Graceful Client UI Degradation: Structuring front-end client rendering pipelines to pause non-essential visual animations during periods of high network congestion while prioritizing core odds updates.
The Technological Evolution of Real-Time Cricket Infrastructure
The transition of sports analysis from post-match statistical reporting to instantaneous ball-by-ball pricing demonstrates the maturity of distributed real-time computing systems. As low-latency edge networks, sensor-driven ball tracking, and automated risk models become standard components of sports data pipelines, platforms can render complex micro-events with precision and speed.
Maintaining system stability under these high-throughput conditions requires ongoing optimization across data ingestion, algorithmic modeling, and network distribution tiers. Systems built on modular microservices, decoupled caching topologies, and automated integrity checks maintain operational reliability, ensuring that live match feeds deliver consistent performance even during peak sporting events.